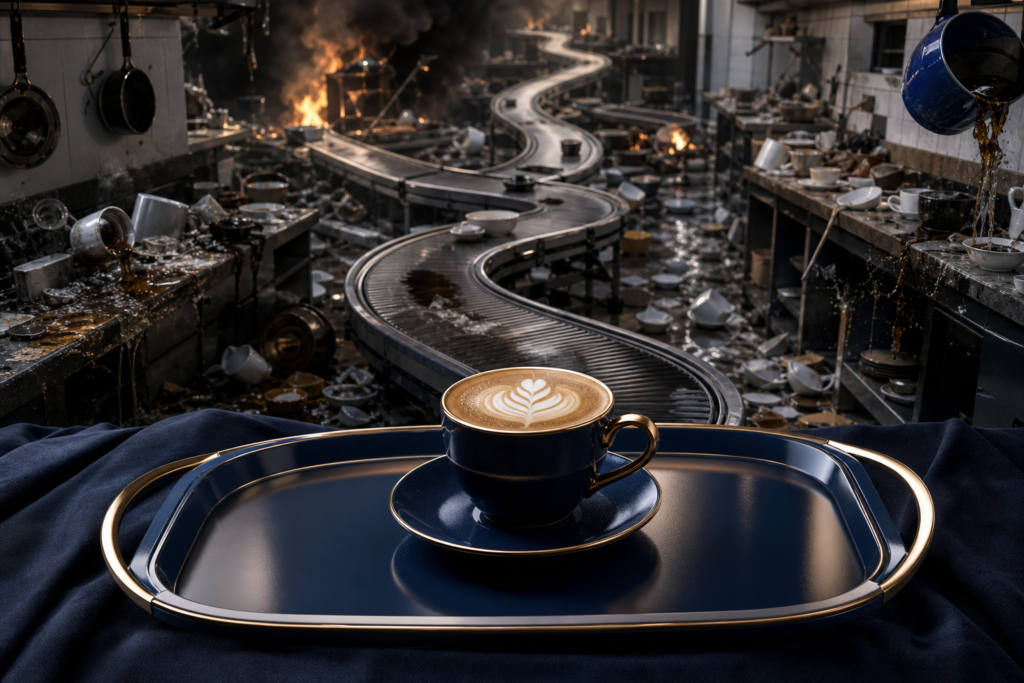
Imagine ordering one coffee at a restaurant.
The waiter returns with a flawless cup: perfect temperature, delicate foam, not a drop on the saucer. You are impressed—until you look behind him and discover that he visited six kitchens, broke twenty plates, charged your card forty-seven times, and started a small fire.
The coffee is correct. The job was not.
That is what it can feel like when an AI agent is “drunk.” It may sound polite and deliver an answer that looks right while its hidden execution path is looping, wasting money, using the wrong tools, passing dangerous arguments, or acting beyond the authority you intended to give it.
The agent is not literally intoxicated. It is behaving unpredictably inside a system that only grades the final cup of coffee.
The “sounds smart” trap
Most of us naturally judge AI by what appears on the screen. If the answer is clear, confident, and well organized, we assume the work behind it was equally disciplined.
That shortcut is reasonable for a simple question. It becomes dangerous when an agent can search files, call APIs, send messages, update databases, run code, spend credits, or publish content.
An agent may reach a correct answer through a bad route. It may also reach a wrong answer through a route that looks perfectly normal in the final summary. Output grading alone cannot tell you which happened.
This is the difference between evaluating a response and evaluating a trajectory. The response is what the agent says at the end. The trajectory is the observable sequence of tool selections, arguments, results, retries, and decisions that produced it.
Catch the agent in the act
You do not need to understand advanced machine learning to inspect a trajectory. Start with three ordinary questions.
Did it choose the right tool? A calculator is useful for arithmetic. A web search is useful for current information. A database update tool is not appropriate when the user only requested a preview.
Did it pass the right information? Choosing the correct tool is not enough. The agent can still use the wrong customer ID, an invented date, an unsafe file path, or a malformed request.
Did it take a reasonable path? Several routes may be valid, so shortest is not always best. But repeated calls with no progress, circular planning, and expensive detours deserve attention.
LangSmith’s agent-evaluation guidance separates final-response evaluation, single-step evaluation, and full-trajectory evaluation. It also notes that exact-path matching can be too strict because more than one route may be correct. A useful evaluator therefore checks required tools, forbidden actions, argument quality, and unnecessary steps—not merely whether every call matches one memorized sequence. LangSmith agent evaluation
Give the agent four bouncers
The PDF that inspired this article uses a nightclub metaphor: put bouncers at the door. The idea is playful, but the architecture is serious.
Bouncer 1: inspect the input
The first gate looks for instructions that should not control the agent. A webpage, email, or uploaded document can contain text designed to override the real task. Treat external content as data, not trusted authority.
This gate can flag suspicious instructions, separate trusted system rules from untrusted content, and require confirmation when a request suddenly expands in scope.
Bouncer 2: validate every tool call
Before a tool touches the real world, check its arguments against a schema and a policy.
Is the customer ID valid? Is the amount within an approved limit? Does the resolved file path stay inside the permitted directory? Is a delete operation allowed at all?
Typed validation tools such as Pydantic can reject malformed structures, but syntax is only the beginning. A perfectly valid JSON request can still ask for the wrong action. You need semantic checks and permission checks as well.
Bouncer 3: verify the proposed result
Before the user sees a claim—or before the system commits a change—compare the result with observable evidence.
For research, that may mean opening the primary source. For code, it may mean running tests. For a database change, it may mean reading the affected record back. For publishing, it may mean requesting the public URL and checking the image, title, and status.
Bouncer 4: enforce the final policy
The final gate asks whether the action is allowed even if every earlier step succeeded.
A refund may require human approval above a threshold. Production access may be read-only. A public post may require a featured image and an unchanged approval fingerprint. This gate converts organizational intent into an enforceable stop condition.
OWASP describes excessive agency as a risk created when an LLM system is given functionality, permissions, or autonomy that can enable damaging actions after unexpected, ambiguous, or manipulated output. The safest fix is not simply a smarter prompt. It is less privilege, narrower tools, and approval where consequences justify it. OWASP Excessive Agency
Test offline, trace live
Before deployment, build a small test set. Include normal tasks, ambiguous requests, missing data, conflicting sources, malicious instructions inside documents, tool failures, and loops that should terminate.
Run those tests whenever you change the model, prompt, tools, or permissions. OpenAI’s evaluation API provides structured datasets, testing criteria, runs, and graders so versions can be compared consistently rather than judged from one demo. OpenAI Evals
Testing does not end at deployment. Production creates combinations you did not imagine. Capture traces of tool calls, latency, errors, token use, retries, and policy decisions. OpenTelemetry defines a trace as the path a request takes through an application, composed of spans that record individual operations. That makes it a useful foundation for observing agent workflows across services. OpenTelemetry traces
Alert on behavior, not just crashes: unusual loop depth, repeated failed calls, sudden cost increases, new tool combinations, denied actions, and changes in completion time.
The expert lesson: control the state transitions
At the deepest level, a reliable agent is not a free-form conversation attached to powerful tools. It is a controlled state machine with probabilistic reasoning inside deterministic boundaries.
The model may propose the next action. Code validates the structure. Policy decides whether the action is permitted. The tool executes with minimum privilege. Independent checks observe the result. Logs preserve what happened. High-impact transitions pause for approval. Every reversible change keeps a rollback path.
This architecture does not make the model deterministic. It makes the consequences governable.
A perfect coffee should not excuse a burned kitchen. Stop grading only what arrives on the tray. Watch the route, install the bouncers, test before release, and trace the agent while it works.
That is how you sober up an AI system without taking away the intelligence that made it useful.