Introduction
Imagine asking questions about every document, code file, and note on your computer — and having each answer link back to the exact file and line where the information lives. No cloud API keys, no data leaving your machine, no separate model server to keep running. Lilbee does exactly that: it bundles a local LLM runtime, document ingestion, vector search, and citation tracking into a single executable that runs on your Mac, Linux box, or Windows PC [S1][S3].
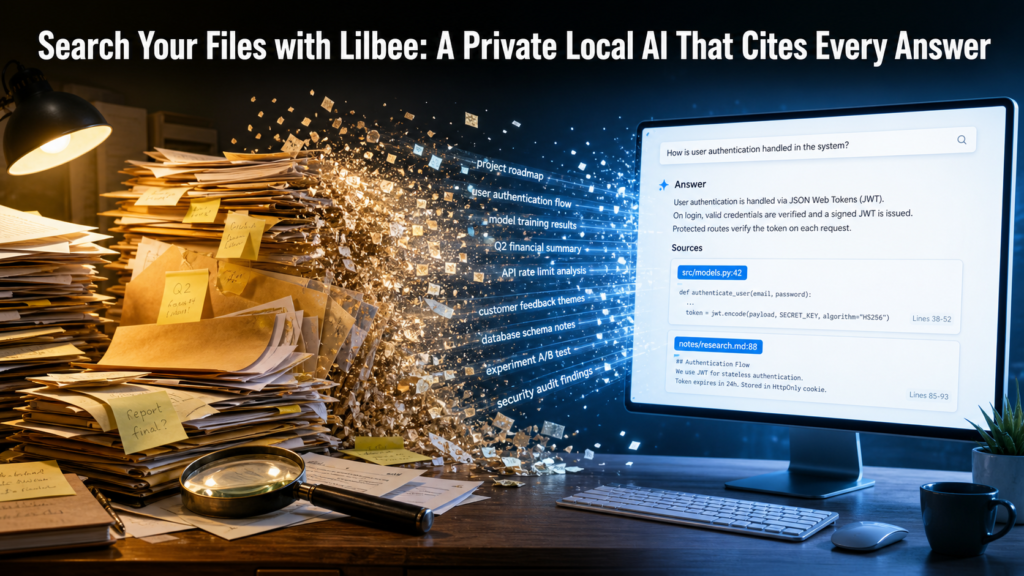
Lilbee isn’t another chatbot frontend. It’s a private search engine for your own files, powered by local models via llama.cpp [S5]. You point it at a folder — your project directory, your Obsidian vault, your research papers — and it indexes everything into a LanceDB vector store. Then you ask questions in conversational English, and lilbee retrieves the relevant chunks, passes them to a local model as context, and returns an answer with clickable citations [S1][S5]. When something isn’t in your library, it tells you instead of inventing one.
This tutorial walks through installing and running lilbee for the first time, indexing your files, and getting your first cited answer. By the end, you’ll have a working private AI search engine on your machine, no Docker or model-server assembly required.
Prerequisites
Lilbee runs on Apple Silicon and Intel Macs (macOS 11+), Windows 10/11, Linux x86_64, and Linux ARM64 (including Raspberry Pi 4+). The minimum specs are 8 GB of RAM and 2 GB of disk; 16–32 GB is recommended if you plan to keep several models warm at once. No GPU is required — CPU-only works — but an Apple Silicon Mac, NVIDIA card (CUDA), AMD card (ROCm), or Intel Arc GPU will speed things up significantly.
If you have an older CPU from before 2013 (pre-AVX2 Intel or pre-Zen AMD), use the lilbee-compat build instead. The standard builds bundle the Vulkan loader on Linux and the appropriate GPU runtime for each platform.
Installing Lilbee
Lilbee offers several installation paths. The simplest is the standalone binary — a single self-contained file with its own Python runtime, llama.cpp, and all dependencies bundled. No pip needed, no Docker, no separate model server to configure [S1]. Download the release for your platform from the GitHub releases page.
On macOS, Homebrew is the cleanest option:
“bash brew tap tobocop2/lilbee && brew install lilbee “
On Linux, install from the AUR (paru -S lilbee), use Nix (nix run github:tobocop2/lilbee), run the Flatpak (flatpak install lilbee io.github.tobocop2.lilbee), or download the standalone binary directly. Windows users can use Scoop (scoop install lilbee) or grab the .exe from the releases page.
If you prefer to manage lilbee as a Python package — useful for scripting or library import — install it with pip or uv, including the engine extra from lilbee’s own package index:
“bash pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/cpu/ “
The --pre flag is required because all PyPI releases are pre-releases [S2]. The [engine] extra pulls in the bundled llama-server from lilbee’s own PEP 503 index, since CUDA and ROCm wheels exceed PyPI’s 100 MB per-file limit [S1]. Use the cpu, cu125, rocm, or metal index depending on your hardware.
On NVIDIA hardware specifically, install the CUDA build by appending -cuda: brew install tobocop2/lilbee/lilbee-cuda. The CUDA runtime is bundled; you only need the NVIDIA driver.
After installing, verify the tool chain works in under a minute:
“bash lilbee self-check “
This downloads about 90 MB, runs an inference pass and an embedding pass, and prints SELF-CHECK PASSED on success [S1]. It’s the fastest way to confirm your installation is ready before pulling models.
First Start: Choosing Your First Model
Running lilbee with no arguments launches the full-screen terminal app (TUI). On first run, it opens on the model catalog — a grid of cards showing every model the engine can run on your machine. Each card carries a fit chip that tells you whether the model will fit on your hardware.
Click or select a chat model to pull it. The first model you install becomes the active chat model, and a toast confirms when chat is ready. You’ll also want an embedding model — lilbee prompts you to pick one the first time you use Search mode, /remember, or index documents.
The catalog has two tabs: Local lists native GGUF models from the HuggingFace catalog and any OpenAI-compatible backends like Ollama or LM Studio you already have. Frontier lists cloud models (Anthropic, Gemini, OpenAI) when you’ve configured API keys — useful for occasional off-corpus questions but optional.
Indexing Your Files and Notes
Once you have a chat model loaded, you’re in the chat screen. To make lilbee useful, you need to give it something to search. Press /add and type or tab-complete a path — a single file, a whole directory, or even a URL. The indexing job runs in the background in the Task Center, so you can keep chatting while it works [S4].
If a file with the same name is already indexed, add skips it by default. To re-index a changed document in place, delete it first with /delete name, or run lilbee add --force <path> from the CLI.
For code repositories, lilbee chunks prose and code differently — comments and docstrings are grouped separately from function bodies — so each retrieved chunk keeps its meaning and you get more useful results than a naive line-based splitter. You can also create per-project libraries so work projects, personal notes, and research papers don’t all mix into one search space [S1].
Searching with Cited Answers
The toggle above the prompt switches between Search and Chat mode (F3 flips it). In Search mode — the default — every prompt goes through document retrieval first. Lilbee pulls the most relevant chunks from your indexed files, passes them to the chat model as context, and the reply ends with a Sources block of clickable citations. Each citation links to the exact file and line number, so you can jump straight to the source of any claim [S4].
When retrieval finds nothing usable, lilbee says so plainly instead of answering from the model’s general knowledge — you won’t get hallucinations posing as facts. Switch to Chat mode for an off-corpus answer from the model’s training data.
This is where lilbee pays off. Instead of opening a dozen tabs, grep across directories, and hoping your memory of where you read something is right, you ask: What did I write about database indexing last month? and get back a paragraph drawn from your actual notes, with a line-level citation you can follow.
Extending to Your Agent and Editor
Lilbee exposes five surfaces — TUI, CLI, MCP server, REST API, and Python library [S1][S4]. The MCP server (lilbee serve mcp) exposes lilbee_search and lilbee_add tools that any MCP-aware coding agent — Claude Code, Cursor, Zed, Continue — can call to answer from your real files instead of guessing function names. The same engine works two ways: it’s an Encarta ’99 over your own files, or a reference layer that makes your coding agent cite your actual codebase and API docs.
If you use Obsidian, install the lilbee community plugin from the Obsidian plugin browser. It brings the full search, chat, and wiki experience into your vault, with the same file:line citations and per-project library separation. All data stays on your machine [S1].
Troubleshooting and Rollback
- Model won’t load: Check the catalog’s fit chip. If your GPU is too small, switch to a smaller GGUF quantization (Q4_K_M instead of Q8_0) or the CPU build.
- Slow over SSH: The TUI works over SSH, but redraws are as fast as your link. Use a local terminal or forward COLORTERM from a truecolor-capable local terminal.
- Wrong results: Adjust retrieval depth and distance thresholds in
/settings. Values persist toconfig.tomlacross restarts. - Factory reset: Type
/resetin the TUI. This clears your index and config but leaves downloaded models on disk. Remove models with/remove <name>, or delete the data directory entirely. - Uninstall: Standard package-manager removal.
pip uninstall lilbeefor Python;brew uninstall lilbeefor Homebrew.
Bottom Line
Lilbee replaces the usual stack of a separate model server, a vector database, and an MCP gateway with a single executable. For the afternoon tinkerer who wants to ask questions of their own files without cloud dependencies, it’s a compelling one-command-to-running solution. The trade-off is that it’s young software — under 50 GitHub stars at the time of writing and in active beta — so expect interface changes between releases. But if private, cited, local search of your documents sounds like something you’ve been assembling from half a dozen tools, lilbee is worth trying this evening.
Sources
- [S1] tobocop2/lilbee — The whole local AI stack in one executable — GitHub (2026-03-05)
- [S2] lilbee 0.6.90b427 — PyPI — Python Package Index
- [S3] lilbee — the whole local AI stack in one executable — lilbee.sh
- [S4] Usage Guide — lilbee — tobocop2/lilbee (docs)
- [S5] Architecture — lilbee — tobocop2/lilbee (docs)